About us
Resources
Console
ZooProxy provides reliable proxies for web scraping and large-scale data collection, with global coverage and flexible IP options.
99.92% network availability
Free geo-targeting
Average response time < 0.5s
Global resource distribution
Key Proxy Challenges in Web Scraping
01|Stable and Reliable Access
Continuous requests can be affected by network fluctuations, leading to failed access and disrupted data collection.
02|Geo-Targeted Content
Different locations may show different content, requiring location-specific proxies to collect local data.
03|Intelligent Request Scheduling
Web scraping involves many requests, so managing request rates and concurrency helps ensure smooth data collection.
04|Large-Scale Scraping Efficiency
Proxy resources, concurrency, and response speed can impact data collection efficiency at scale.
How ZooProxy Powers Web Scraping
Flexible IP Rotation & Sticky Sessions
Supports IP rotation and sticky sessions, allowing you to switch IPs or maintain stable connections based on your data collection needs.
HTTP, HTTPS & SOCKS5 Support
Supports HTTP, HTTPS, and SOCKS5 protocols with API and username/password access for seamless integration with Python, Puppeteer, and fingerprint browsers.
High Concurrency & Low Latency
Supports high-concurrency requests with average response times under 0.5s, delivering stable connections that shorten large-scale extraction cycles.
Precise Global Geo-Targeting
Covers countries, regions, and cities worldwide with precise city-level targeting, making it easy to gather accurate, localized market data.
Web Scraping Proxy Use Cases
From e-commerce data collection to market research, web scraping proxies help businesses access public web data across regions for a wide range of analytics and business needs.
E-commerce Data Collection
Collect public product specs, stock, pricing and reviews. Stable residential proxies support product management, competitor analysis and operational decisions.
Price Monitoring
Continuously track prices, promotions and stock changes across sites. Precise geolocation captures localized data to follow market trends and optimize pricing.
Market Research
Gather industry information, market trends and consumer data across countries and regions, accessing multi-region public data to understand target markets and competition.
SEO Data Collection
Collect search results, keyword rankings and competitor public data. Local IPs in different regions capture localized SERPs for keyword optimization, traffic analysis and SEO decisions.
Brand & Competitor Monitoring
Continuously collect brand information, product updates and public market data with flexible proxy scheduling to monitor brand sentiment, competitor changes and industry trends.
Content & Data Aggregation
Collect news, articles and industry information from multiple public websites, then aggregate multi-source data through flexible proxy configuration and API access.
Whether you need multi-region collection, high-concurrency scraping or large-volume data transfer, ZooProxy offers flexible proxy types and plans for every web scraping project.
Residential Proxies
Starting from $0.38 /GB
Buy Now Buy NowISP Proxy
Starting from $1.80 /IP
Buy Now Buy NowHow to Use Proxies for Web Scraping
Complete these 4 simple steps to configure your proxies and start web scraping with ZooProxy.
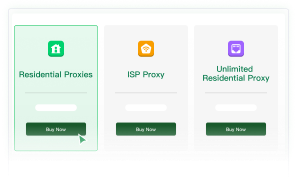
Step 01:Choose a Proxy Type
Choose dynamic residential, static ISP, or unlimited residential proxies based on your project needs
Step 02:Configure Proxy Settings
Select your target country, region, or city, then set IP rotation or sticky sessions to match your scraping task.
Step 03:Connect Your Scraping Tools
Get your proxy details via API or username and password, then integrate them with Python, Puppeteer, or fingerprint browsers.
Step 04:Start Data Collection
Launch your scraping tasks and adjust proxy settings based on target websites, collection volume, and data requirements.
Why Choose ZooProxy Web Scraping Proxies
ZooProxy offers flexible proxy options and reliable support for web scraping projects of all sizes.
Global IP Coverage
Access IPs across multiple countries and regions for web scraping and global market research.
Diverse Proxy Types
Choose from dynamic residential, static ISP, and unlimited residential proxies to fit your traffic and connection needs.
99.92% Network Uptime
Reliable connections help minimize disruptions and support continuous data collection.
Flexible Pricing Plans
Choose from plans billed by traffic, IP count, ports, or bandwidth to match your project scale and budget.
Fast Network Response
Average response times under 0.5 seconds help reduce wait times and improve data collection efficiency.
24/7 Technical Support
Get 24/7 technical support to help resolve issues related to proxy configuration, connections, and usage.
This section covers common issues you may encounter during use, and you can independently refer to it for assistance in efficiently conducting your business
A web scraping proxy routes requests through a proxy IP to collect public web data from different regions for price monitoring, market research, and large-scale data collection.
It depends on your needs. Dynamic residential proxies suit IP rotation, static ISP proxies support consistent IP usage, and unlimited residential proxies suit high-traffic scraping projects.
ZooProxy supports API or username/password access for tools such as Python, Puppeteer, Selenium, and compatible HTTP clients.
Yes. Depending on the proxy type, you can use IP rotation or sticky sessions to suit your scraping needs.
Adjust request rates, concurrency, IP selection, and rotation settings to help reduce errors. Always follow target websites' terms of service.
Pricing depends on the proxy type and billing model. ZooProxy offers plans billed by traffic (GB), IP count, ports, or bandwidth to fit your project scale and budget.
Use ZooProxy web scraping proxies to power multi-region collection, high-concurrency crawling, and large-volume transfer within your existing workflow.